An AI that answers a question can make a mistake and produce a poor response. An AI that acts inside a system can make a mistake and cancel a payment, change a record, send a message to the wrong audience or open a request nobody approved.
That is the difference between using AI as an interface and using AI as part of an operation.
In recent days, security companies have started treating this second scenario as its own category. Cisco announced red teaming and observability capabilities for agents. CrowdStrike introduced an interruption and control mechanism for AI actions. The message behind those announcements is straightforward: when a model gains tools, permissions and the ability to execute, it also needs technical limits.
The right question is not whether a company should use agents. It is this:
who can stop the AI when an execution goes off course?
An agent is not just a model
An LLM, or Large Language Model, interprets context and produces text, code or a likely decision. It is not, by itself, an application with authority to change a system.
An agent appears when that reasoning capability is connected to a set of tools. It can find a customer, check stock, assemble a report, create a task, send a message or call an API.
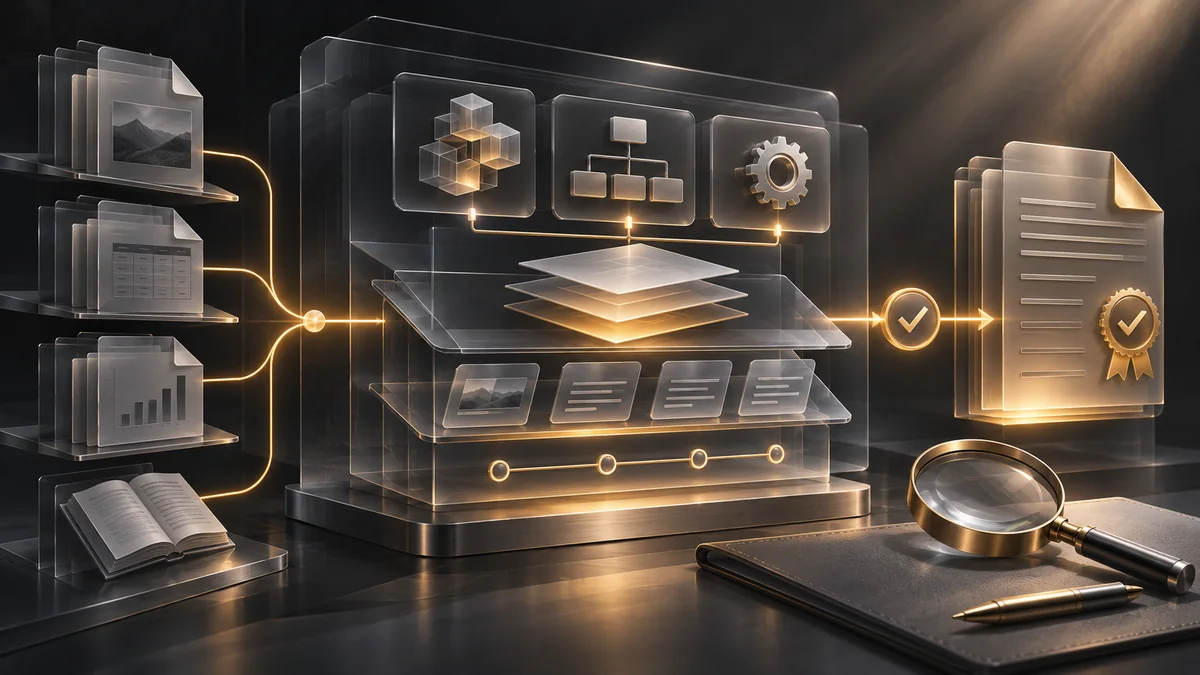
In practice, a production agent brings together at least five layers:
- model: interprets the request and proposes a path;
- orchestrator: manages steps, memory, execution rules and retries;
- tools: the functions and APIs that allow action;
- identity and permissions: define what each agent can access;
- observability: records what happened and supports investigation.
The model works with probability. The tool, however, performs a deterministic action. If an agent calls cancel_payment(id), the system does not interpret intent: it cancels or blocks.
That is why a sound architecture separates two things that are often mixed up: AI can propose an action; the application must authorize it.
A kill switch is not a red button
The term kill switch sounds dramatic, but it describes a practical need: stop execution capacity before unexpected behavior becomes operational impact.
In a real system, this should not be only a button on a screen. It needs to be a set of controls able to:
- stop scheduled executions and new calls;
- cancel work waiting in a queue;
- revoke temporary tokens and session credentials;
- block a specific tool without taking down the entire system;
- preserve execution state for later analysis;
- return the process to a manual path when needed.
The important detail is that the interruption needs to happen outside the model. Asking the AI itself to "stop acting" is an instruction. Revoking its permission to call an API is a control.
This is the same distinction between hiding a button in the browser and validating permission on the server. An interface can guide usage. The rule that protects the operation needs to exist where execution happens.
Least privilege also applies to AI
The principle of least privilege says that an identity should receive only the access it needs to perform its function. It is not a new cybersecurity rule. What changed is that the agent now also needs its own identity.
An agent that answers customer questions does not need access to finance. An agent that drafts reports should not edit production data. An agent that creates tasks does not need to delete projects.
In practice, that asks for clear architectural decisions:
- separate service accounts for each agent;
- short-lived, limited-scope tokens;
- small, specific and verifiable tools;
- policies written in code before an API call;
- isolation between test and production environments;
- limits on volume, financial value and repeated attempts.
Instead of giving execute_sql(query) to an agent, it is safer to offer functions such as list_overdue_orders() or create_purchase_request(data). The second option narrows the possible action space and makes intent auditable.
Not every action deserves the same level of autonomy
Autonomy is not a binary choice. It can vary according to the impact of a decision.
A simple classification helps design the flow:
- Query: the agent reads data and answers. It changes nothing.
- Reversible action: it creates a task or prepares a draft that can be corrected.
- Sensitive action: it updates an important record, sends external communication or moves a queue. It requires an additional rule and a record.
- Critical action: it approves a payment, deletes data, changes permission or closes a contract. It requires human approval and stronger authentication.
This is where two useful terms apply. Human in the loop means a person approves before execution. Human on the loop means the AI executes within limits while a person monitors alerts and can intervene.
The first makes sense for high-impact decisions. The second can work for repetitive, reversible and well-bounded actions.
Observability is more than knowing whether it worked
In software, observability is the ability to understand a system's internal behavior through its records, metrics and traces. For AI agents, that does not mean keeping only the final response.
An execution needs to record, securely and proportionately:
- which objective was requested;
- which context and data were used;
- which tools were called and with what parameters;
- which policies allowed, blocked or requested approval;
- how much time, cost and how many retries the task consumed;
- which identity authorized the action;
- which result the tool returned.
These records help reveal whether an agent failed, repeated work, received a malicious instruction or attempted an action outside its scope. They also make it possible to improve the process without relying on impressions or the memory of whoever followed the case.
There is an essential caution: observing does not mean storing everything without criteria. Prompts, documents and responses can contain personal or strategic information. Audit trails need retention policies, masking, access control and privacy compliance.
The real test begins before production
Before releasing an agent, a company needs to test it as it would test any exposed part of its operation. That includes simulating situations that never appear in a demo:
- contradictory or hidden instructions in documents;
- an attempt to make the agent ignore a policy;
- incomplete, duplicate or outdated data;
- API failure followed by an improper retry;
- repeated events that cause duplicate actions;
- an attempt to leave the permission scope;
- abnormal request volume or unexpected cost.
This exercise is called red teaming. Instead of waiting for someone to find a weakness in the operation, the company itself tries to provoke a deviation in a controlled environment. The goal is not to prove that AI is perfect. It is to discover where the system needs a barrier, approval or better rule.
Autonomy needs an owner
Agents can reduce repetitive work, respond faster and prepare decisions with more context. That value appears when AI is placed close to the real process, not when it receives unlimited access to everything.
Before delegating an action to an agent, it is worth answering three questions:
which decisions can it support, which actions can it execute and who can stop it?
AI can be autonomous. Responsibility cannot.
Comments
No comments yet. Start the conversation.